The problem
A working application still needs reproducible infrastructure, controlled releases, observability, and a practical way to recover when a deployment is unhealthy.
Why this matters to me
Bring the infrastructure and application delivery lifecycle into version control, and connect deployment decisions to metrics rather than manual inspection alone.
My role
Contributed infrastructure as code and delivery automation for the NT548 team project. The project and its architecture are shared team work; the source repositories retain the original attribution.
Technical approach
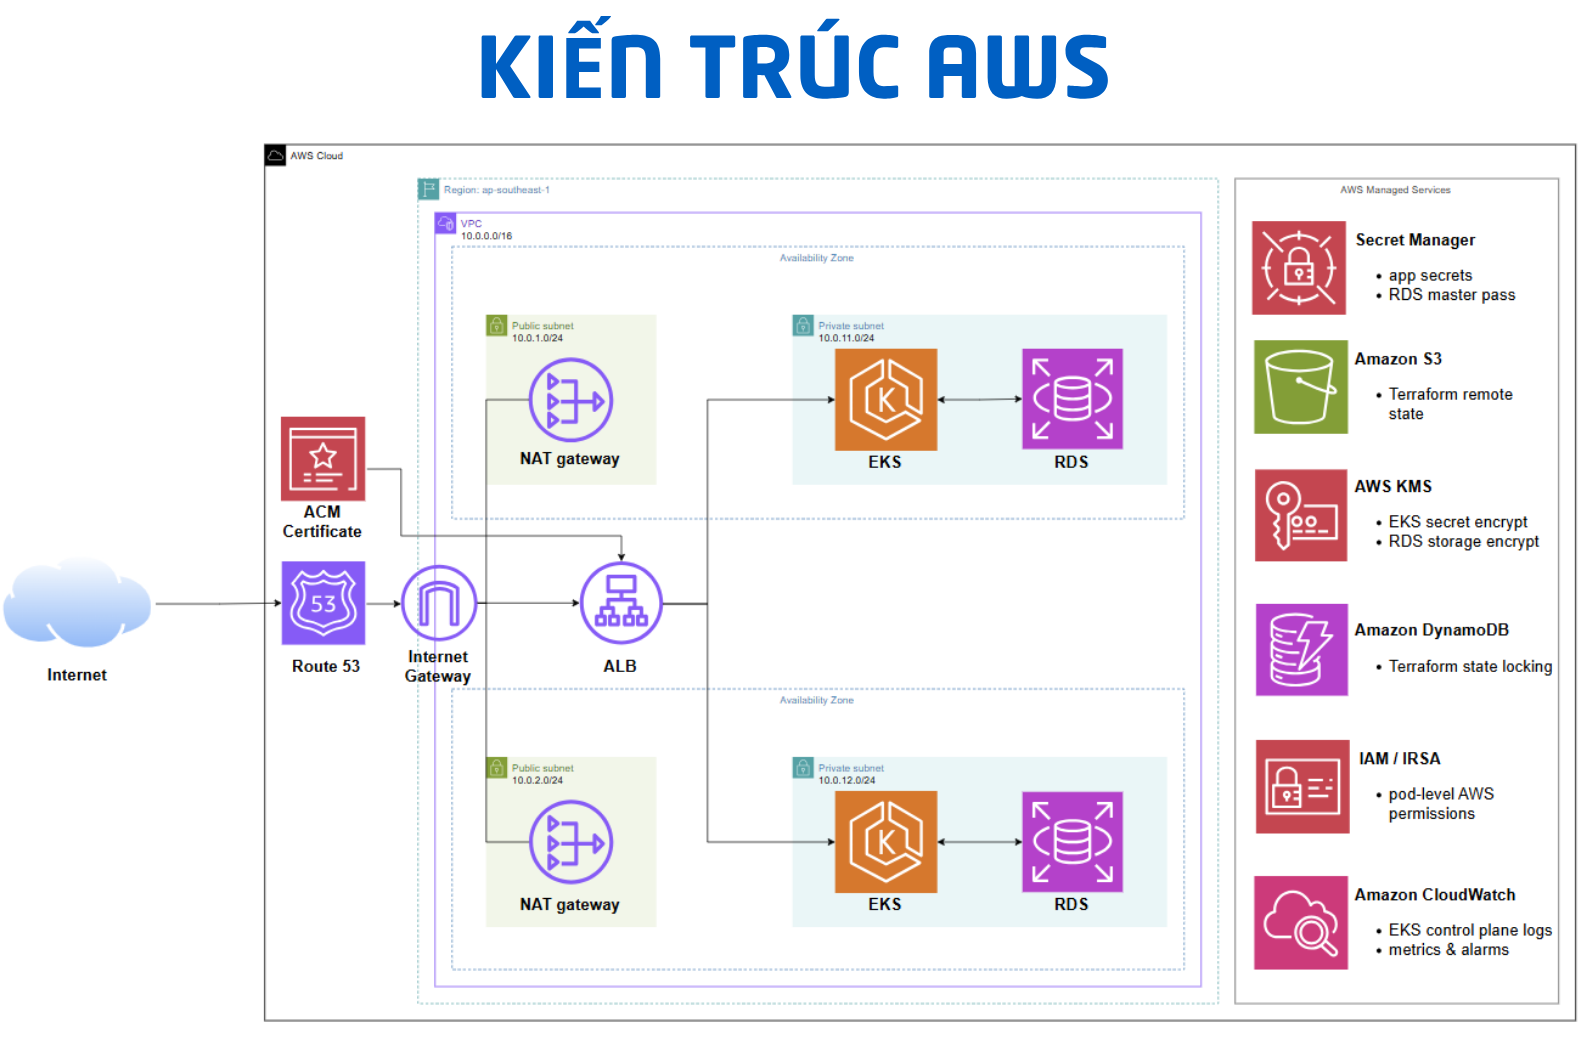
- Provisioned AWS infrastructure using Terraform with separate states, S3 storage, and DynamoDB state locking.
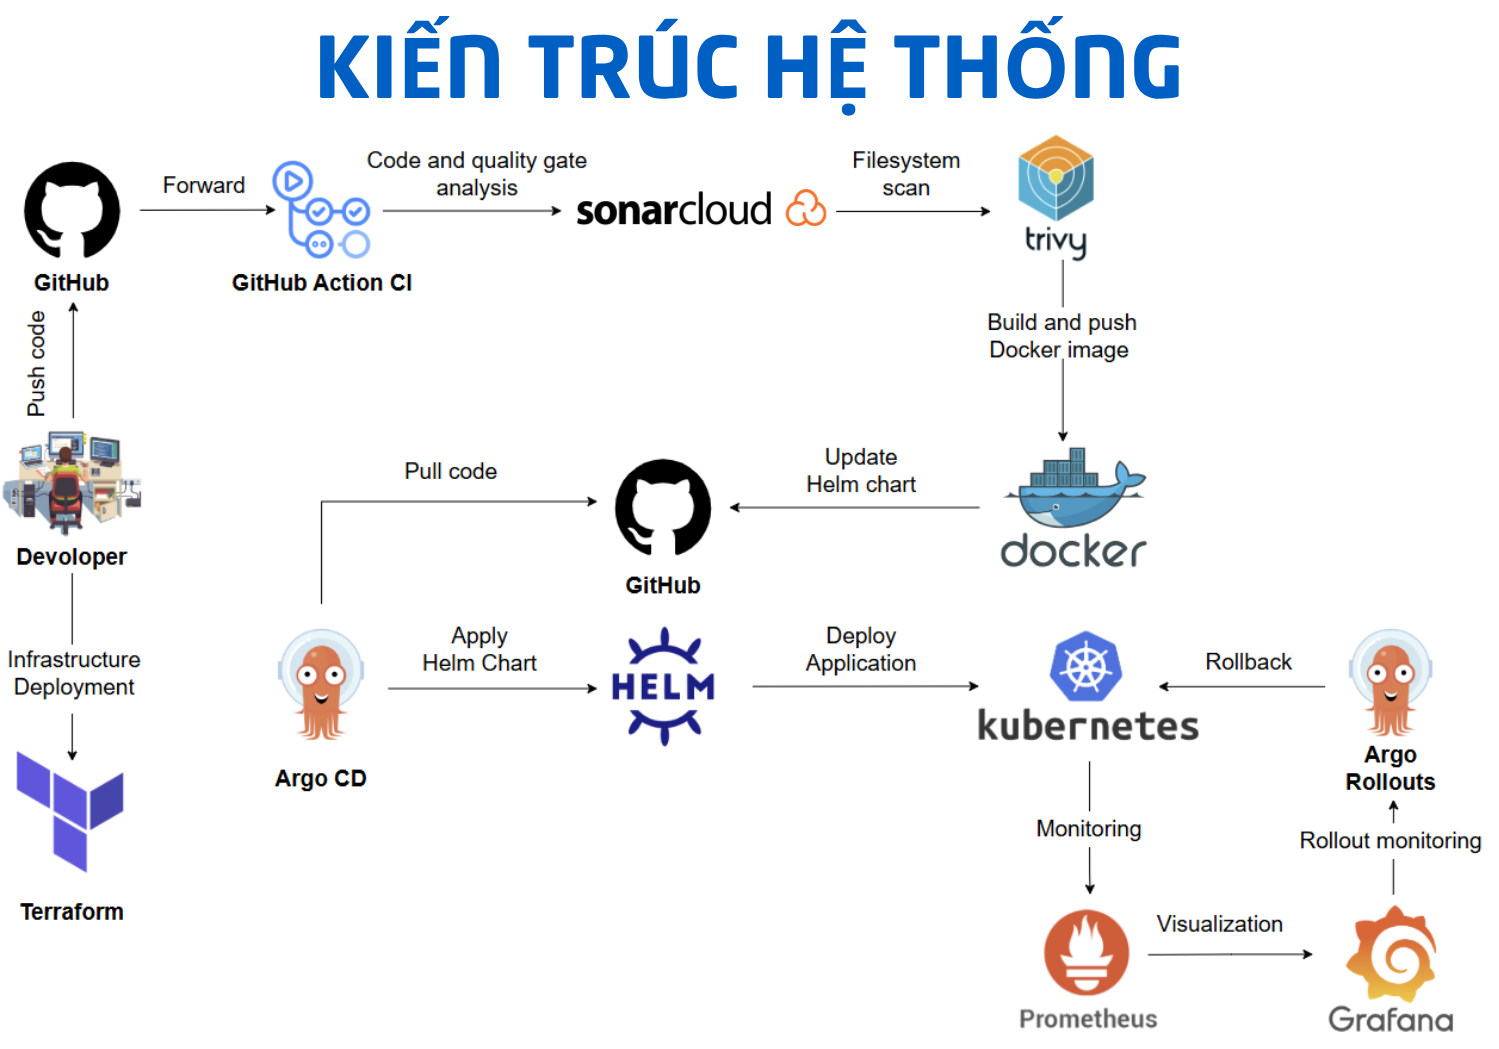
- Connected GitHub Actions to a separate GitOps configuration repository consumed by ArgoCD.
- Used Argo Rollouts for Blue/Green releases, with Prometheus analysis and rollback behavior.
- Included cluster observability, external secrets, network policies, and CI security scanning.
Results & current status
Source code, architecture diagrams, and a Vietnamese project report are available in the team repository. This portfolio does not claim an always-on production service or a newly repeated cloud benchmark.
Limitations & open questions
- The EKS stack is provisioned on demand, so the original demo domain may be offline.
- This is an educational team project. Architecture and implementation should be evaluated in that context.
The delivery pipeline